5 JVM Heap OOM Patterns You Can Reproduce on Your Laptop
I’ve been digging into JVM out-of-memory behavior across G1, ZGC, and Shenandoah, and I put together a set of reproducible labs. Each one is a real OOM scenario you can trigger on your own machine — no cluster required. The repo’s test suite runs each scenario in under a minute on a standard laptop (verified in CI across JDK 11/17/21/25).
The 5 Patterns
1. Unbounded Cache
The classic. A Map that grows forever because nobody evicts entries. Every web app has written this bug at least once.
Map<String, byte[]> cache = new HashMap<>();
while (true) {
    // No eviction, no size bound — just keeps growing
    cache.put(UUID.randomUUID().toString(), new byte[1024]);
}
Reproduce: ./run.sh scenario-01-unbounded-cache broken
Diagnose: Generate a heap dump with -XX:+HeapDumpOnOutOfMemoryError, open it in Eclipse MAT → Dominator Tree → sort by retained heap. The HashMap (and its Node[] table) will own 90%+ of the heap. Right-click → Path to GC Roots → exclude weak references to find what’s pinning it.
Fix: Bounded cache with eviction (Caffeine, Guava CacheBuilder, or manual LRU). The fixed version uses the same workload with a size-capped cache.
2. Oversized Batch
One allocation that’s bigger than the heap. Common in data pipelines that load an entire dataset into memory before processing.
// 250MB batch vs 64MB heap — dies on a cliff, not a staircase
byte[] batch = new byte[250 * 1024 * 1024];
Reproduce: ./run.sh scenario-02-oversized-batch broken
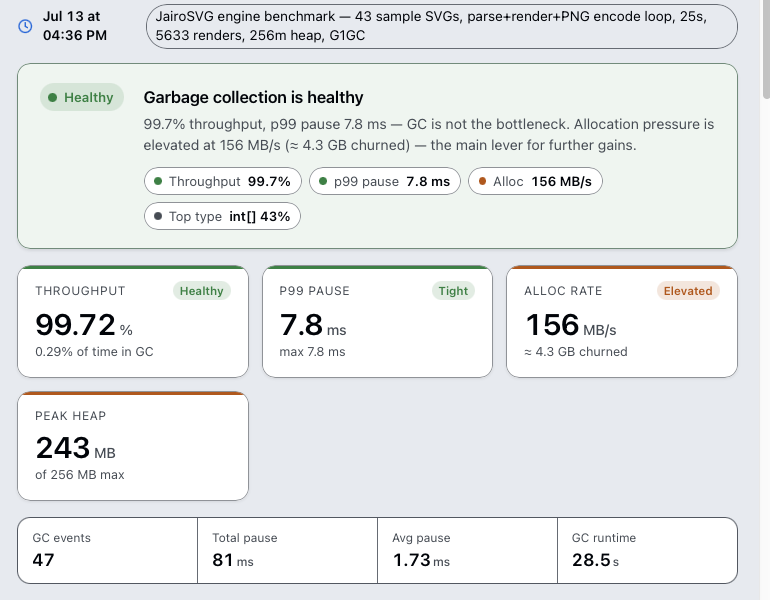
Diagnose: This one doesn’t need a heap dump — the stack trace points directly at the allocation site. The lesson is in the GC log: unlike the cache scenario (gradual staircase), this is a single cliff. One moment healthy, next moment dead.
Fix: Chunked reads sized for the heap. Process in batches that fit comfortably within -Xmx.
3. Report Builder Retention
A StringBuilder (or report object) that accumulates data across requests and never gets cleared. The reference is held longer than you think.
Reproduce: ./run.sh scenario-03-report-builder broken
Diagnose: Heap dump → Dominator Tree → look for a single large char[] or byte[]. Unlike scenario 1, the retainer isn’t a cache — it’s the product being built. Check Path to GC Roots to find the builder object holding it.
Fix: Stream output incrementally (write to disk/network as you go) instead of accumulating in memory.
4. ThreadLocal Leaks
The sneaky one. ThreadLocal values aren’t cleaned up when a thread returns to a pool, so they accumulate across requests in app servers.
private static final ThreadLocal<List<String>> context = new ThreadLocal<>();

void handleRequest() {
    try {
        context.set(new ArrayList<>());  // grows per request
        // ... do work ...
    } finally {
        context.remove();  // THIS LINE is the fix. Without it: leak.
    }
}
Reproduce: ./run.sh scenario-04-threadlocal-leak broken
Diagnose: Heap dump → search for ThreadLocalMap → inspect entries. Each pooled thread holds a growing list. The GC log won’t show a clear staircase because the growth is per-thread, not global — this one is invisible without a heap dump.
Fix: remove() in finally, always. No exceptions.
5. Leaked Connections
Database connections (or any pooled resource) that aren’t closed. The pool exhausts, threads block waiting, and heap fills with queued requests.
Reproduce: ./run.sh scenario-05-leaked-connections broken
Diagnose: Thread dump first (not heap dump): jstack <pid> → threads blocked on pool acquisition. Then heap dump to see the request queue backing up. Two dumps, two different stories.
Fix: try-with-resources + explicit deregistration. The fixed version shows the same workload completing cleanly.
What Surprised Me
Running these across collectors, the failure shapes differ dramatically. Shenandoah’s concurrent approach means it survives gradual leaks much longer than G1 (in my testing, roughly an order of magnitude on the unbounded cache scenario) — but a sudden oversized allocation kills it faster because there’s less headroom for a stop-the-world rescue. The “best” collector depends entirely on your failure mode, not on benchmark throughput.
These are preliminary observations from the repo’s benchmarks, not peer-reviewed results. I’m writing a paper on this now — the repo is the companion artifact.
Try It Yourself
Everything’s on GitHub with Docker Compose:
https://github.com/amits710/jvm-oom-field-guide
Each lab has:
- A reproducer script (
./run.sh scenario-NN broken) - A diagnosis guide (
diagnosis.md— GC log signature, heap-dump walkthrough, triage checklist) - The fix (
./run.sh scenario-NN fixed— same workload, no OOM) - A
comparemode that runs both back-to-back
CI runs the full suite on JDK 11, 17, 21, and 25. If you’ve hit OOM patterns I haven’t covered, open an issue — that’s how the repo grows.
Found a mistake, or something to add? Edit this page on GitHub
Amit Sonar
Senior Software Engineer with 14 years of experience building backend systems at Microsoft, LinkedIn, and Bloomberg. Focused on JVM performance, he builds reproducible OOM labs so developers can break things safely on a laptop before they break in production.